
Quantitative finance has a reputation problem. To people outside it, it sounds like black boxes and people in fleeces who have never met a customer. To people inside it, it has lately come to mean machine learning, as if the discipline arrived with the hardware. Neither is right, and since most of my working life has been spent doing it, in energy markets and then more broadly, I want to describe what it actually is, what it is for, and what the arrival of AI does and does not change.
What it is
A price is affected by interest rates, by supply and demand for the thing itself, by what consumers are doing, by politics, by company results and by how everyone else feels about all of the above. No one can weigh those by hand, and the more information there is, the less possible it becomes. Quantitative finance is the structured answer to that problem. You write down a model that relates the things you can measure to the price you care about, you test it against the past, and you use it to evaluate the present. The model does not remove uncertainty. It makes uncertainty something you can put a number on and argue about, rather than a feeling.
In practice the models are used for a short list of jobs: pricing instruments, measuring how much risk a portfolio is carrying, working out how assets move together, testing whether a trading idea would have worked, looking for places where two prices disagree with each other, and watching how volatility is changing. Everything on this site about correlation and volatility is a small piece of that list.
Oil Analytics
Energy was where I learned to do this properly, because energy is where the models have to be physical. The price of crude depends on production, shipping, storage, refinery capacity, seasonal demand, government policy and the state of the world economy, and those interact. A refinery turns crude into petrol, diesel and jet fuel; a petrochemical plant turns feedstocks into the materials half of manufacturing depends on; a problem at one stage moves the prices at every other stage. You cannot understand the oil price from production figures alone, and most people who try end up being surprised by it.
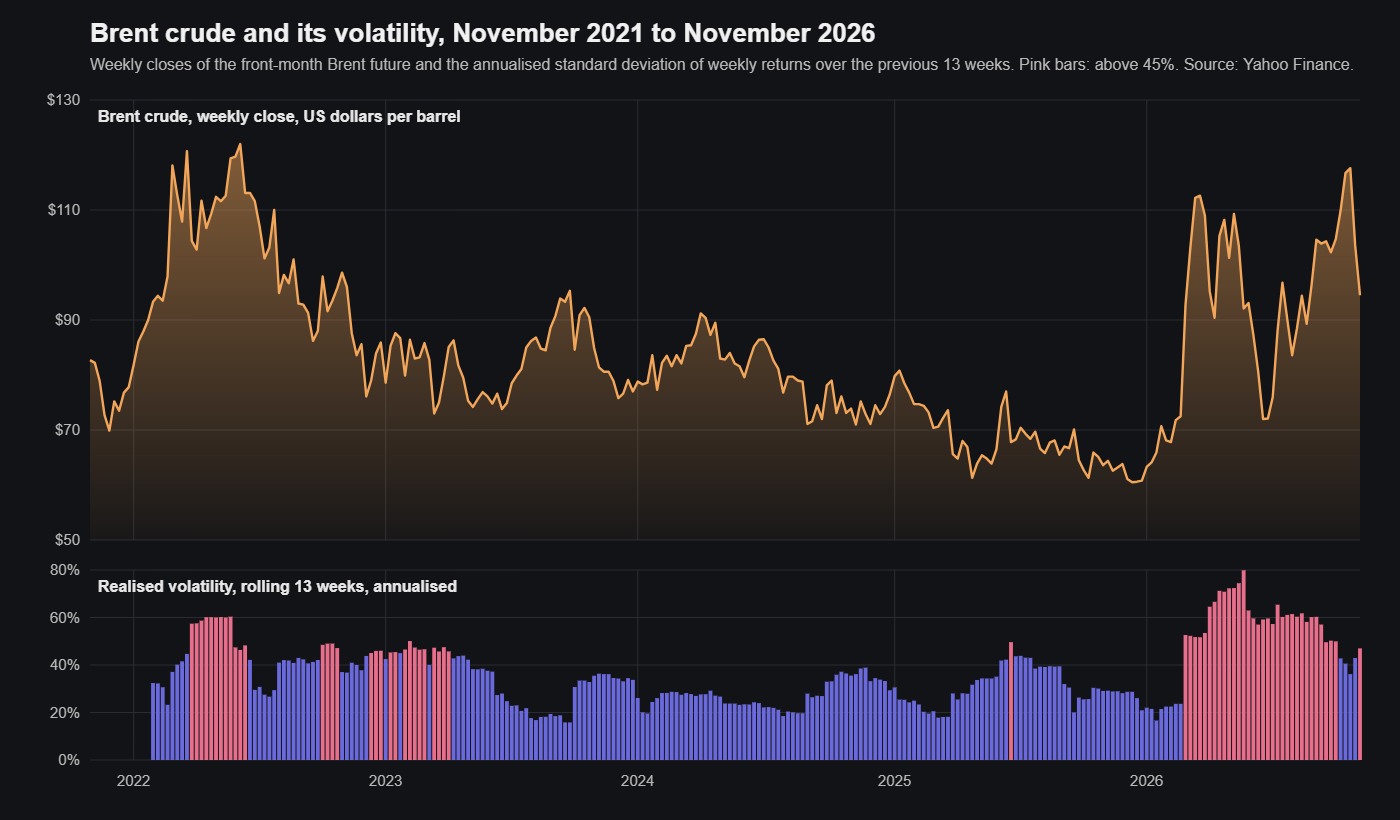
Five years of Brent, with its realised volatility underneath, is a reasonable picture of why the models have to be physical. None of the big moves is explained by the oil price itself; every one of them is explained by something happening to supply, to refining, to policy or to demand, and the volatility bars show that those episodes arrive in clusters rather than at random, which is exactly what a model built on the physical chain predicts and a model built on the price series alone does not. At Oil Analytics, where I was a partner, we built a framework that modelled the whole chain. It combined derivatives analysis, equity research and corporate advisory work on top of detailed models of the refineries and petrochemical plants themselves. The modelling ran at two levels. Zonal models looked at the combined capacity of all the facilities in a supply region, which is what you need to understand regional balances and flows. Local models went plant by plant, estimating what each refinery or cracker was likely to be doing given its configuration and the margins in front of it. Put together, the two levels told you what was happening underneath the headline price, usually before the headline price reflected it. The framework was eventually taken on as a Bloomberg data provider, which is the point at which a model stops being an internal view and has to survive strangers checking it.
Optima Cap
The fund I set up afterwards, Optima Cap, was a London-based quantitative macro energy fund, and it was an attempt to take what the Oil Analytics work had taught me and run money on it systematically. The approach used mathematical models, low-frequency algorithms and some machine learning across futures, options, currencies and equity indices. Low-frequency matters: this was not high-speed trading, it was a set of views about the macro picture, expressed through models, with rules around them.
The rules are the part people underestimate. A systematic process has to define, in advance, when a position may be opened, how large it may be, what would prove the idea wrong, when exposure should be cut, how different positions interact with each other, and how losses are controlled. Writing those down does something a discretionary trader rarely manages, which is to take fear and overconfidence out of the decision at the moment it is made. The model is not smarter than the person. It is calmer.
Risk is the whole job
A strategy can be right on average and still fail if the risk is handled badly, because markets do not deliver the average. They deliver the days when correlations jump, liquidity vanishes and volatility doubles, and a book that looked diversified on Monday is one position by Thursday. I have written about correlation elsewhere on this site, and the short version is that relationships between assets are not constants, and any model that treats them as constants is going to be wrong on the day it matters.
So the risk framework is not an add-on. Position limits, diversification that is checked rather than assumed, stops, scenario analysis, liquidity monitoring, controls that scale positions to volatility, and stress tests that ask what happens if everything moves against you at once. The aim is not to avoid losses, which is impossible, but to make sure that no single position or event can do harm the book cannot recover from.
What AI changes
Machine learning adds a layer to all of this, and the layer is real. Traditional models follow rules an analyst wrote down. Learning systems can find patterns across far larger and messier datasets than any analyst could read: news flow, changes in trading behaviour, unusual relationships between prices, alternative data that did not exist a decade ago. Used well, that makes the models better at noticing things and faster at updating their assumptions.
What it does not do is remove the need for someone to be responsible. A model that has found a pattern in the past does not know why the pattern exists or whether the conditions that produced it are still in place. Someone still has to decide whether the data can be trusted, whether the model has been tested honestly, whether the strategy fits the market as it is now rather than as it was, whether the risk is acceptable, whether the output can be explained to a colleague in plain words, and what the system might do in conditions it has never seen. In a volatile market that oversight is the difference between a tool and a liability.
The most important thing I have learned in this field is that the technology is there to support judgement, not replace it. Models, algorithms and learning systems help you organise information and evaluate opportunities. Their value depends entirely on the quality of the data going in, the discipline of the strategy around them, and the strength of the risk framework underneath. Get those three right and the tools are a genuine edge. Get them wrong and the tools will find a way to lose money faster than you could have on your own.